Efficient Multi-Scale Deformable Attention on GPUs
A journal offprint set by a careful compositor: serif prose in a 34em measure, italic notes in the margin, one thin red rule where the article begins.
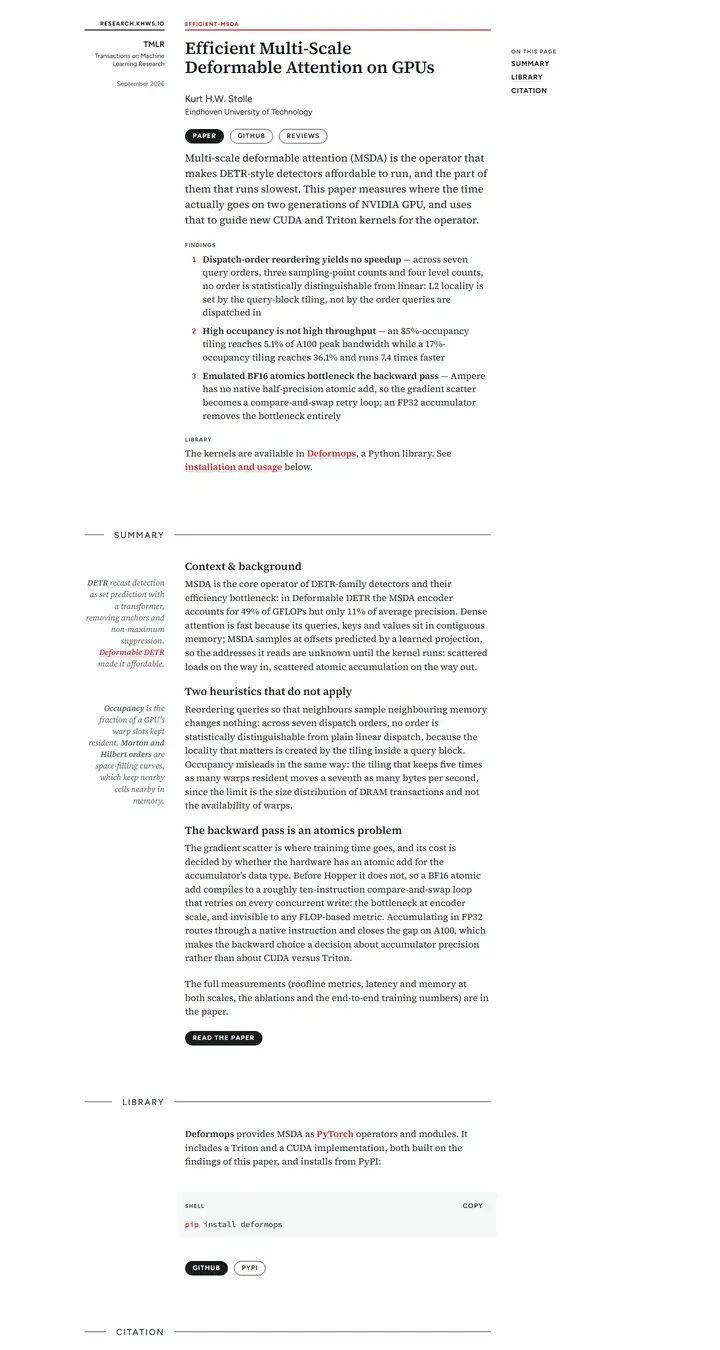
Checked against the rendered page. No figures, tables or video on the page. Right rail position is set by a script variable (--right-rail-left). Dark scheme exists via footer toggle; light documented as default.
Why it is here
Most distinctive page in the pool. Editorial serif type, a left metadata rail, italic margin sidenotes, numbered findings and ruled section dividers make it read like a well-set journal article. The measure is comfortable and the hierarchy is clear.
Overview
Color Palette
Typography
Source Serif 4
Efficient Multi-Scale Deformable Attention on GPUs
Abstract · Method · Results · BibTeX — 0123456789
Figtree
Efficient Multi-Scale Deformable Attention on GPUs
Abstract · Method · Results · BibTeX — 0123456789
Source Code Pro
Efficient Multi-Scale Deformable Attention on GPUs
Abstract · Method · Results · BibTeX — 0123456789
Spacing & Shape
Page Modules
Guidelines
More like this
CRAFT: Training-Free Cascaded Retrieval for Tabular QA
A tidy product manual in pale blueprint blue, where every stage wears its own colored edge.
Efficient Self-Evaluation for Diffusion Language Models via Sequence Regeneration
A tidy stack of rounded cards washed in a blue-violet-apricot dawn, signed with a gradient wordmark.
FIGMA: Towards FIne-Grained Music retrievAl
A music journal on warm paper: a heavy Newsreader headline under a red kicker, big red serif numerals for the results, and figures resting in soft cream frames.
GuideDog: A Real-World Egocentric Multimodal Dataset for Blind and Low-Vision Accessibility-Aware Guidance
A quiet monograph page: one serif column, oxblood ink for the links, and a table that blushes only at its own row.
LaMI: Augmenting Large Language Models via Late Multi-Image Fusion
A careful conference handout: Noto Serif headings, navy outlined buttons and soft grey bands taking turns.
PairCoder++: Pair Programming as a Universal Paradigm for Verified Code-Driven Multimodal and Structured-Artifact Generation
A crisp white product page: a blue announcement strip, ink-black pill buttons and every figure on a soft-shadowed card.